
Crawlability means Googlebot can access your page. Indexability means Google has decided to store and rank that page in its index. These are two separate processes, and confusing them is one of the most common reasons site fixes fail.
Most technical SEO write-ups lump these two together, which leads site owners to fix the wrong thing. You block crawling when the real issue is indexing signals, or you rewrite meta tags when Googlebot cannot even reach the page. Neither approach works.
Who this is for: This article is for website owners, in-house marketers, and small business operators in the Philippines who have used Google Search Console and seen pages flagged as “not indexed” but are unsure whether crawling or indexing is the actual bottleneck. Not for: developers doing a first pass at robot exclusion or anyone looking for a beginner breakdown of how search engines work from scratch.
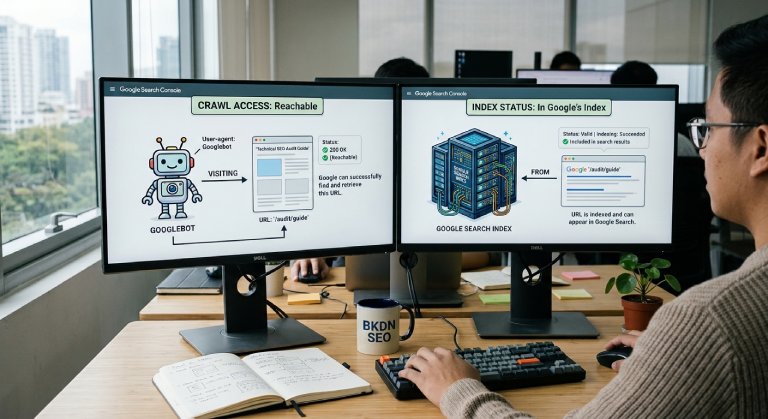
Table of Contents
ToggleKey Takeaways
- Crawlability and indexability are separate stages. Fixing one does not fix the other.
- A page can be crawled and still not indexed. Search Console labels this “Crawled – currently not indexed.”
- Robots.txt controls crawling. A noindex tag controls indexing. Using both on the same page can backfire.
- The URL Inspection tool reports the crawl result and the index result in separate sections. Read both before you change anything.
- Naming the broken stage first saves hours of rework and keeps you from making things worse.
Know Where Pages Get Stuck
A page moves through four steps before it can appear in search. Google finds the URL, crawls it, processes what it found, and then decides whether to index it. Each step fails for different reasons.
Discovery depends on links and sitemaps. Google finds most URLs by following links from pages it already knows, or by reading your XML sitemap. A page with no internal links pointing to it and no sitemap entry may never get found.
Crawling depends on access and server health. Robots.txt rules, redirect problems, and slow or failing servers can all stop Googlebot from fetching the page.
Indexing depends on the page itself. Google checks whether the page offers something unique, whether another URL is the better version, and whether you told Google to leave it out. Passing the crawl step does not guarantee a spot in the index. The same goes for a clean 200 status code.
Once you see the pipeline this way, Search Console messages become easier to read.
Read the Search Console Status First
Open Search Console and go to Indexing, then Pages. Google calls this the Page indexing report, and it replaced the older Coverage report. The “Why pages aren’t indexed” table gives a reason for each group of URLs. Two statuses cause the most confusion because they sound alike.
“Discovered – currently not indexed” means Google knows the URL exists but has not visited it. Google typically postponed the crawl to avoid overloading your site, so the last crawl date stays empty.<sup>2</sup> This is a crawl-side problem. On a small business site, the usual causes are weak internal links, a slow server, or a sitemap packed with low-value URLs.
“Crawled – currently not indexed” means Googlebot visited the page and chose not to store it, at least for now. This is an index-side problem. The cause is usually the page itself, such as thin content, a near-duplicate of another page, or a canonical tag pointing somewhere else.
| Signal in Search Console | Stage | Where to Start |
|---|---|---|
| Discovered – currently not indexed | Crawl | Internal links, sitemap, server speed |
| Crawled – currently not indexed | Index | Content quality, duplicates, canonical tag |
| Blocked by robots.txt | Crawl | Robots.txt rules |
| Excluded by “noindex” tag | Index | The noindex tag |
Rewriting copy will not help a page Google has not visited yet. Adding links will not help a page Google visited and rejected. The status tells you which one you are dealing with.
Confirm the Stage With URL Inspection
The report shows volume. The URL Inspection tool shows specifics for one page. Paste the URL into the bar at the top of Search Console. The result lists crawl details (last crawl date, crawl status, HTTP response) apart from index details (whether the page is indexed and why not). Treat them as two separate answers.
Work through these checks in order:
- Check robots.txt. Open the robots.txt report in Search Console settings. Google retired the older robots.txt tester. If the URL is blocked, fix that first and stop there.
- Check the HTTP response. A long redirect chain or a 5xx server error can stop Googlebot from fetching the page.
- Look for a noindex directive. Check the meta robots tag in the HTML head and the X-Robots-Tag in the HTTP headers. On WordPress sites, also check Settings, then Reading, for the “Discourage search engines from indexing this site” box. It is often left on after a site launch.
- Check the canonical tag. Google treats it as a strong hint. When it points to a different URL, Google may index that URL instead of yours.
- Run a site search. Type site:yourdomain.com/page-slug into Google to see whether the URL is indexed.
Search Console data runs behind real time. A page may show as not indexed while Google is still working through it. Wait about 3 days after a fix before you retest.
Robots.txt Blocks Crawling, Noindex Blocks Indexing
This is where the two stages collide, and where many teams make the costly mistake.
Robots.txt tells Googlebot not to visit a URL. A noindex tag tells Google it may visit but should not store the page. The catch is that noindex only works when Google can read the page. Put a noindex tag on a page that robots.txt blocks, and Google never sees the tag. Google’s John Mueller has confirmed this.
It gets worse. When other sites link to a blocked URL, Google may still list it in the index with no content shown. Google knows the page exists. It just cannot read it. Search Console flags these as “Indexed, though blocked by robots.txt.”
Website audits turn up this exact conflict often. Staging pages and thin URLs get blocked in robots.txt but never get a noindex tag. They end up as bare listings that dilute your site quality signals. Match each tool to its job:
Use robots.txt for URLs you do not want crawled at all, such as internal search result pages. It does not hide anything from people who have the link, so keep private areas like admin pages behind a login.
Use noindex for pages visitors can use but that should not appear in search, such as thank-you pages. Leave these pages crawlable so Google can read the tag.
To remove a page from the index, add noindex and leave the page open to crawling. Block it in robots.txt only after Google has dropped it.
Noindex has one trade-off. Googlebot still visits those pages, so thousands of thin noindex URLs can pull crawl time away from your priority pages. On a small site this rarely matters. On a large site, the better move is to cut the number of low-value pages.
Fix the Problem at the Right Stage
Once you know the stage, the fix gets specific.
When Google Has Not Crawled the Page
Give Googlebot a clear path. Link to the page from pages Google already crawls often, such as your homepage, main service pages, and related blog posts. Keep your sitemap limited to pages you want indexed, so important URLs do not compete with junk. Then check your server speed, since a struggling server is a common reason Google delays a crawl.
When Google Crawled but Did Not Index the Page
Fix the page, not the access. Start with thin content. For example, imagine a service page for aircon cleaning in Malaybalay City that lists only a phone number and two sentences. Google has little reason to store it. Add what a customer needs to decide: what the service covers, the process, the areas you serve, and the questions people ask.
Next, look for duplicates. Separate pages for every location with nearly identical text give Google a reason to pick one and skip the rest. Merge them into one stronger page, or rewrite each one around details that are truly different. Then confirm the canonical tag points to the version you want indexed.
After the fix, use URL Inspection and request indexing. Google says it can take a week or so for a new page to be crawled and indexed. Monitor the Page indexing report over the following two weeks.
Removing a robots.txt block works the same way. It restores crawl access and nothing more. Google still makes its own indexing decision, so unblocking a page does not guarantee it will appear in search.
Name the Stage First, Then Fix It
Every technical fix starts with one question: is Google failing at access or failing at inclusion? The answer decides everything that follows. A page that Google never reached needs a path. A page that Google reached and rejected needs a reason to stay.
I run this same diagnostic sequence on every site I audit. I find the broken stage, handle the on-site fixes, and flag server-level items for your developer. If your pages are sitting unindexed in Search Console, reach out at bukidnonseo.com and we can start with a structured audit before you touch a single line of robots.txt.
Sources:
1 https://support.google.com/webmasters/answer/7440203
2 https://seocrawl.ai/blog/google-search-console-crawled-currently-not-indexed
3 https://searchengineland.com/?p=434708
4 https://ppc.land/google-may-index-pages-blocked-by-robots-txt/