
You open the Page indexing report in Google Search Console and find an important page sitting under “Crawled, currently not indexed.” Google visited it. Google read it. Google still left it out of search results.
That is frustrating, especially when the page is one you built to bring in customers. This guide shows you how to tell whether the page needs help, what usually holds it back, and which fixes are worth your time.
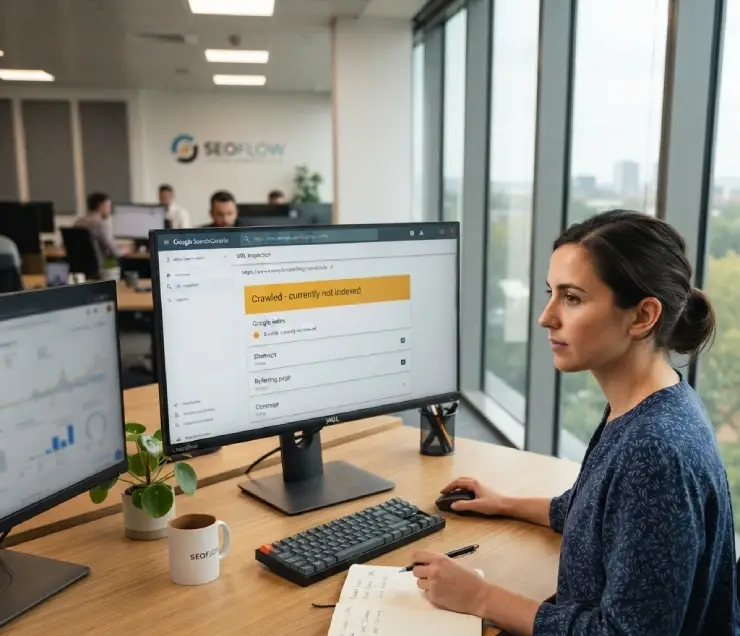
Table of Contents
ToggleWhat This Status Tells You
Search works in stages. Google first finds a URL, then crawls it (fetches the page and reads its content), then decides whether to store it in its index. Only indexed pages can appear in search results.
“Crawled, currently not indexed” means your page passed the first two stages and stalled at the third. Google describes it in one line: the page was crawled but not indexed, and it may or may not be indexed in the future.¹ Google also says you don’t need to resubmit the URL for crawling.¹
Keep it separate from “Discovered, currently not indexed.” That status means Google knows the URL exists but hasn’t crawled it yet, usually because a crawl might have overloaded your site.¹ With your status, Google already read the page. Your focus shifts from access to value: does the page give Google a reason to keep it?
Decide Which Pages Deserve to Be Indexed
Google tells site owners not to expect every URL on a site to be indexed.¹ Duplicate pages, filtered or sorted versions of a page, and URLs that redirect elsewhere are normally left out on purpose.¹ A long list under this status does not mean your whole site has a problem.
Sort the affected URLs into two groups. Service pages, location pages, and blog posts that should earn traffic deserve your time. Tag archives, feeds, parameter URLs, and old pages with no purpose can stay where they are.
Small sites can make this easy. Google notes that a site with fewer than 500 pages probably doesn’t need the Page indexing report at all. Search for site:yourdomain.com/exact-page-url instead, and you will see right away whether Google has indexed that page.¹
Some pages should stay out of the index. Use a noindex tag for those, not a robots.txt rule. Google warns that a robots.txt block prevents Google from seeing the noindex tag, and it isn’t the recommended way to keep a page out of search results.
Confirm the Status With a Live Test
In Search Console you can click “Request Indexing.” It can be useful for urgent fixes, but it’s not a magic button. Repeatedly requesting indexing for pages with quality or technical problems rarely helps.
Use “Request Indexing” after you fix the underlying issue. If nothing changed besides the request, Google will usually ignore repeated attempts until it sees improvement.
- Good use: after fixing a noindex tag, broken structured data, or major content upgrade.
- Poor use: requesting indexing for thin or duplicate pages without changes.
The report can lag behind your site. Google points out that you may have fixed a problem after the last crawl, so compare the crawl date for the URL against the date you made your changes.¹
Open the URL Inspection tool, paste in the page, and click Test live URL. Then check three things:
- Indexing allowed: This field shows whether a noindex tag or header is blocking the page. If it is, remove the tag, test again, and request indexing.¹
- Canonical URLs: Compare the canonical you declared with the one Google selected. When Google picks a different URL, it treats your page as a duplicate of that one.¹
- Tested page screenshot: Click View tested page to see how Google renders the page. Missing text, images, or sections point to a rendering problem.¹
Noindex tags and robots.txt blocks have their own reasons in the report, so they are not the usual cause of this status.¹ The live test still catches them in seconds, which makes it worth running before you spend hours rewriting content.
Watch for soft 404s too. Google uses that label for a page that shows a friendly “not found” message without returning a real 404 code.¹ A page with almost no content can look like one to Google. Add real information to the page, or return a proper 404 code when the page is truly gone and has no replacement.¹ Either fix gives Google a clear signal about what the page is.
Raise the Quality of Pages That Matter
When the technical checks come back clean, look at the page itself. A crawled page that stays out of the index is usually a content problem. The page may be thin (it says little), repetitive, or too close to pages Google already has.
For example, imagine a catering business with separate pages for wedding catering, birthday catering, and party catering. Each page runs 250 words of nearly identical copy. Google has little reason to index all three, because they answer the same question in the same way.
Start by searching your target topic and reading the pages that already rank. Ask what they cover that yours doesn’t. Then rebuild your page around the answer:
- Add first-hand detail: Include real photos, your actual process, local specifics, and examples only you can offer.
- Match search intent: Answer the question the searcher typed, in the order they would want it answered.
- Merge near-duplicates: Combine overlapping pages into one stronger page, then redirect the old URLs to it with a 301 redirect.
- Cut pages with no purpose: Remove them, or add a noindex tag, so they stop competing for attention.
Skip padding. Adding 500 words of filler to a weak page doesn’t make it more useful. A focused 600-word page that solves one problem beats a bloated page that circles it.
Key Takeaways
- This status means Googlebot visited your page and chose not to add it to the index, at least for now.
- Google says the page may or may not be indexed in the future, and you don’t need to resubmit it.¹
- Not every URL needs to be indexed. Focus on the pages that bring in customers.
- Most fixes come down to page quality, duplicate content, internal links, and a few quick technical checks.
- Request indexing once, after you make a real change, then give Google time to respond.
Give Google a Path to the Page
Google can only crawl a page it can find. According to Google, a page must be linked from a known page or listed in a sitemap.¹ A page with no internal links pointing to it is called an orphan page, and it often looks unimportant to search engines.
Add links to the page from related pages that are already indexed. Use descriptive anchor text, such as “wedding catering menu options,” instead of “click here.” Place the link where it helps the reader, not in a block of links at the bottom of the page.
Your sitemap needs attention too. Include only canonical, indexable URLs, and keep it updated. Google also suggests a trick for faster validation: build a sitemap that holds only your most important pages, then filter the report by that sitemap before you ask Google to check your fix.¹
Request Indexing After the Fix, Not Before
The Request Indexing button works best once the page has changed in a way Google can measure. Clicking it on an unchanged page asks Google to repeat a decision it already made.
Google notes that individual URL requests have a quota, and asking for a recrawl of the same URL again and again won’t get it crawled any faster.² Google also states that requesting a crawl doesn’t guarantee inclusion in search results, because its systems prioritize high-quality, useful content.²
Follow this order for a single page: fix it, run the live test, then request indexing once. For many pages with the same problem, fix all of them first. Then open the issue details page in Search Console and click Validate fix. Click it only once, because Google asks you to wait until validation succeeds or fails.¹
Plan for a wait. Validation typically takes up to about two weeks, and sometimes longer.¹ Crawling itself can take anywhere from a few days to a few weeks.²
Plugins and “instant indexing” tools follow the same rule. They can send requests faster, but they can’t change Google’s view of your page. The reliable path is a useful page, clean technical setup, and patience. No shortcuts.
Give Your Fixes Two Weeks, Then Recheck
After you publish your changes and request indexing, leave the page alone for a while. Google notes that indexing is never instant, even when you submit a crawl request directly.¹ Constant edits only reset the clock and make it harder to tell which change worked.
Check back after about two weeks. Open URL Inspection and read the last crawl date first. A date before your changes means Google hasn’t seen the new version yet. A date after your changes with the same status means the page still needs more work, so compare it against the ranking pages again and look for what is still missing.
Treat the status as feedback. Google read your page and wasn’t convinced yet, which gives you a clear task: make the page worth keeping, make it easy to find, and make the technical setup clean.
Stuck on a stubborn indexing report? I audit service business websites myself, so you work directly with me and not with an account manager. You get plain-language answers about what is holding your pages back and what to fix first. No shortcuts. No generic templates.
Sources
1 https://support.google.com/webmasters/answer/7440203
2 https://developers.google.com/search/docs/crawling-indexing/ask-google-to-recrawl
FAQ
How to fix a page that is crawled but currently not indexed?
Start by checking for technical issues: use Google Search Console to inspect the URL for crawl errors, soft 404s, or noindex tags. Ensure the page is not blocked by robots.txt, has a valid HTTP status (200), and uses canonical tags correctly. Improve the page quality—add unique, useful content, clear headings, and internal links from relevant pages. Submit the URL for reindexing in Search Console after fixes and monitor server logs to confirm Googlebot access. If the page is thin or duplicate, consider consolidating or enhancing it rather than forcing indexing.
Is 'crawled, currently not indexed' bad for SEO?
Not necessarily. This status simply means Google has crawled the page but hasn’t added it to the index yet. It can be temporary due to low priority, low perceived value, or indexing backlog. However, if many important pages show this status, it can harm organic visibility. Focus on technical health and content quality to improve index chances.
When should I not worry about a page being 'crawled, currently not indexed'?
Don’t worry if the page is low-value by design (e.g., admin pages, utility pages, staging content), intentionally excluded, or recently published and still within Google’s indexing queue. Also acceptable for pages that are intentionally thin or duplicate where you prefer canonical or consolidated versions to be indexed instead.
What does "not indexed" mean?
“Not indexed” means the search engine has not included the page in its searchable index, so it won’t appear in search results. Reasons include noindex directives, crawl errors, low-quality or duplicate content, URL parameters creating non-canonical pages, or temporary processing delays. Use URL inspection tools to see the exact reason and any suggested fixes.
What is the difference between crawling and indexing?
Crawling is the process where search engine bots discover and fetch pages by following links and sitemaps. Indexing is the subsequent step where the search engine processes the fetched content, evaluates its relevance and quality, and decides whether to store it in its index for search results. A page can be crawled but not indexed if it fails indexing criteria or is deprioritized—this is the crawled currently not indexed meaning in practical terms.
Ready to Build Your Online Presence?
Start with a free, no-obligation SEO consultation.
Book Your Free Audit →